
3
Repos
105.3k
Stars
26.2k
Forks
674
Watchers
🏆 Show off this rank
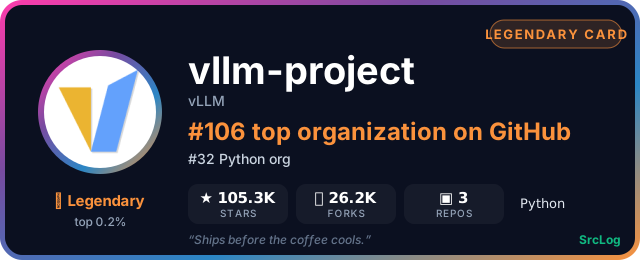


Add it to a GitHub README or profile — the card updates as the ranking changes:
Repositories (3)
vllm
vllm-project/vllm
Python
A high-throughput and memory-efficient inference and serving engine for LLMs
96.9k
24.8k
semantic-router
vllm-project/semantic-router
Go
An open, programmable decision layer for models and compute.
6.4k
1.1k
vllm-metal
vllm-project/vllm-metal
Python
Community maintained hardware plugin for vLLM on Apple Silicon
2k
350